DeepSeek ships V4.1-Flash: asymmetric MoE, 1/4 the KV cache
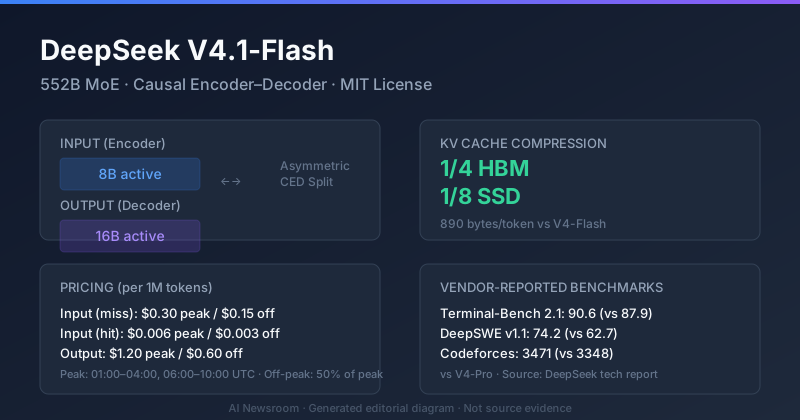
DeepSeek released V4.1-Flash on 2026-09-10 (news post, 2026-09-10) — a 552B-parameter mixture-of-experts model built on a new Causal Encoder–Decoder architecture. With 8B active parameters for input and 16B for output, native multimodal vision, and drastically compressed KV cache, it targets the cost structure of long-running agentic workloads. The API name is deepseek-flash; the weights are MIT-licensed (HF model card).
For agent builders, the headline is the KV cache reduction: DeepSeek reports V4.1-Flash needs “1/4 the HBM and 1/8 the SSD storage of the previous generation” (announcement, 2026-09-10). At 890 bytes per token — a 4× reduction versus V4-Flash and 437× versus V1 (HF model card) — cache-hit costs dominate agent budgets, and this model cuts them sharply.
What’s actually new
Causal Encoder–Decoder (CED). Unlike standard decoder-only transformers, V4.1-Flash splits input and output processing. The encoder handles 8B active parameters for input tokens; the decoder uses 16B for output generation (HF model card). This asymmetric split lets DeepSeek scale input understanding cheaply while reserving capacity for generation.
Native multimodal vision. The vision encoder is DeepSeek-ViT, trained from scratch (HF model card). Image input is native — not bolted on via adapters — supporting both Thinking and non-thinking modes, 1M context, and up to 384K output tokens.
Speculative decoding. DSpark speculative decoding is supported for faster inference throughput (tech report, 2026-09-10).
Open-source inference. The HF model card includes vLLM and SGLang examples (HF model card), and Fireworks offers a serverless deployment (Fireworks listing).
Pricing and routing
New pricing took effect 04:00 UTC on 2026-09-10 (announcement, 2026-09-10). Verified rates from the live pricing page (pricing page, 2026-09-19):
| Tier | Input (cache miss) | Input (cache hit) | Output |
|---|---|---|---|
| Peak (01:00–04:00, 06:00–10:00 UTC) | $0.30 / 1M tokens | $0.006 / 1M tokens | $1.20 / 1M tokens |
| Off-peak (all other hours, weekends, holidays) | $0.15 / 1M tokens | $0.003 / 1M tokens | $0.60 / 1M tokens |
The ~70% output price cut versus V4-Pro ($3.96 peak → $1.20 peak) is real arithmetic — about 69.7% at peak rates. Off-peak, Flash at $0.60 vs V4-Pro at $1.98 delivers the same reduction.
V4-Pro routing status. The Sep 10 announcement stated that starting 04:00 UTC Sep 14, 2026, all deepseek-v4-pro requests would route to V4.1-Flash at Flash rates until V4.1-Pro launches (announcement, 2026-09-10). As of 2026-09-19, the live pricing page still lists deepseek-v4-pro as a separate model with its own pricing. The current footnotes cover legacy model-name routing, off-peak rates, and concurrency — no explicit continuation statement. If you depend on V4-Pro, verify the pricing page on the day you read this.
Benchmarks (vendor-reported)
DeepSeek reports V4.1-Flash ahead of V4-Pro on several agent-oriented benchmarks (tech report, 2026-09-10; HF model card). Independent verification was not located at the time of writing.
| Benchmark | V4.1-Flash | V4-Pro |
|---|---|---|
| Terminal-Bench 2.1 | 90.6 | 87.9 |
| Terminal-Bench 3.0 | 30.0 | 11.8 |
| Terminal-Bench 4.0 | 31.2 | 12.4 |
| DeepSWE v1.1 | 74.2 | 62.7 |
| Codeforces rating | 3471 | 3348 |
| HLE w/ tools | 63.9 | 60.0 |
| AutomationBench | 54.8 | 43.2 |
| Agent’s Last Exam | 31.8 | 25.7 |
| CyberGym | 88.1 | 83.3 |
All figures are from DeepSeek’s tech report or HF model card. Treat them as vendor-claimed.
What to watch
- Independent benchmarks. Agent benchmarks are noisy and vendor-selected. Wait for reproduction before updating evaluation dashboards.
- V4.1-Pro. The announcement positions V4.1-Flash as a precursor. V4.1-Pro will be the real comparison point for flagship workloads.
- Open-source inference. vLLM and SGLang support is documented but not yet battle-tested at scale for 552B MoE with CED. Watch for kernel and framework patches.
- Partner integrations. WorkBuddy (including CodeBuddy) and OpenCode support V4.1-Flash on launch day (announcement, 2026-09-10).
Risks and caveats
- Vendor-claimed benchmarks. Every number above comes from DeepSeek’s tech report or model card. Independent verification was not located at the time of writing.
- KV cache claims. The “1/4 HBM, 1/8 SSD” figures are vendor-reported for global KV cache and persistent SWA KV. Real savings depend on your workload’s context length and batch size.
- Routing uncertainty. The V4-Pro routing change is dated Sep 10; the live pricing page (Sep 19) still lists V4-Pro separately. DeepSeek could change this at any time.
- Pricing may change. The pricing page carries a note that “product prices may vary and DeepSeek reserves the right to adjust them.”
Practical advice for builders
- When to choose V4.1-Flash over V4-Pro. If you run long-context agentic workloads where cache-hit costs dominate, Flash is the clear pick — about 70% cheaper on output tokens and dramatically smaller KV cache. V4-Pro remains available if you need the flagship model for non-agent tasks.
- Off-peak scheduling. Batch flexible workloads outside peak hours (01:00–04:00, 06:00–10:00 UTC) to halve costs. Weekends and Chinese public holidays are fully off-peak.
- HF weights. The model is MIT-licensed. Sampling parameters are documented in the model card.
- Open-source inference. vLLM and SGLang examples are on the HF page. Check for updates before deploying — 552B MoE with CED is a new architecture.
Sources
| # | Source | URL | Date |
|---|---|---|---|
| 1 | DeepSeek API Docs news (Sep 10, 2026) | https://api-docs.deepseek.com/news/news260910 | 2026-09-10 |
| 2 | DeepSeek pricing page | https://api-docs.deepseek.com/quick_start/pricing | live |
| 3 | Hugging Face model card (MIT) | https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash | live |
| 4 | DeepSeek-V4.1 Tech Report (PDF) | https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash/blob/main/DeepSeek_V41_Tech_Report.pdf | 2026-09-10 |
| 5 | Fireworks serverless listing | https://fireworks.ai/models/deepseek-ai/deepseek-v4p1-flash | live |